Last week I learned MuJoCo with a single pendulum. This week I moved to the real robot. The goal: take the trained walking policy from Diego López’s project, run it on the Unitree G1 in my own MuJoCo setup, and understand every number that goes in and out.
The robot walked. Then it refused to turn on the spot. Finding out why led me to a second policy, Unitree’s own from unitree_rl_mjlab, and a small experiment.
All the code is in the exercises/ folder.
Setting up the G1
The G1 model file describes the robot’s body. It has no floor, no motors and no starting pose. I added these with MuJoCo’s MjSpec, which lets you edit a model in Python before you compile it:
spec = mujoco.MjSpec.from_file("robot/g1.xml")
apply_collision_settings(spec)            # which parts touch, how the feet grip
add_floor(spec)
actuator_names = add_position_actuators(spec)   # 29 motors, gains from motor specs
add_init_keyframe(spec, actuator_names)         # knees-bent starting pose, pelvis at 0.76 m
apply_solver_settings(spec)               # 5 ms timestep = 200 physics steps per second
model = spec.compile()
The full function is build_g1_model in g1_utils.py.
One surprise: with the policy’s gains, the robot cannot stand on its own. It slowly sinks and falls over. The gains are soft on purpose. The trained policy is what keeps the robot balanced. Without it, a humanoid is just an inverted pendulum.
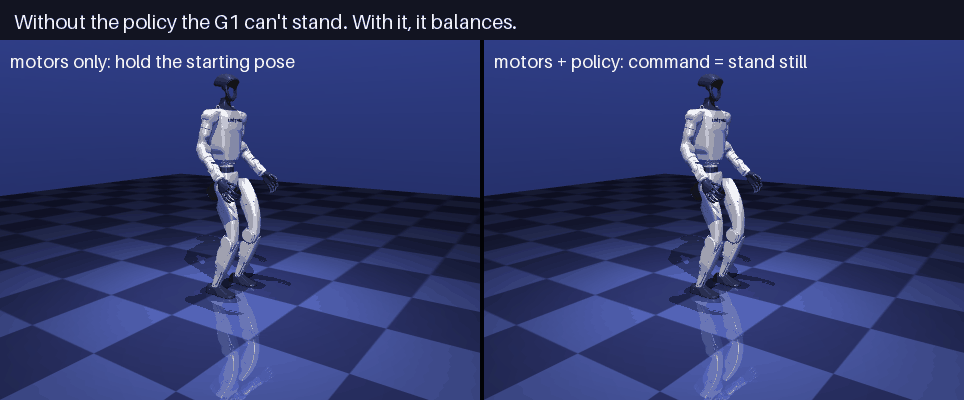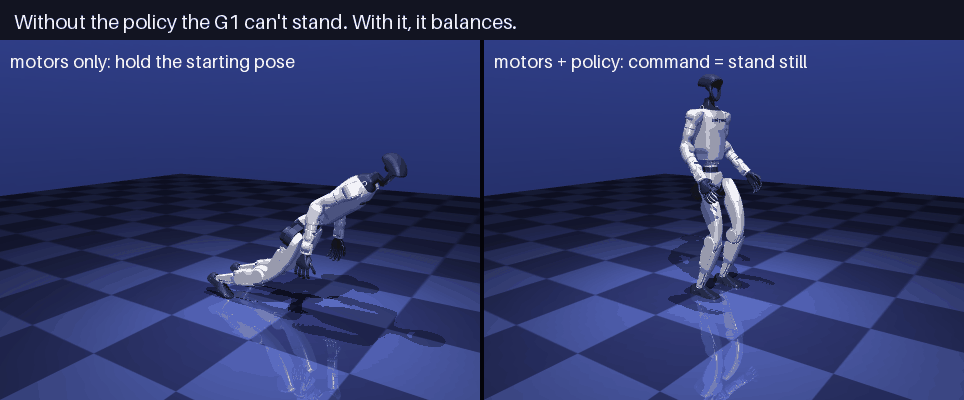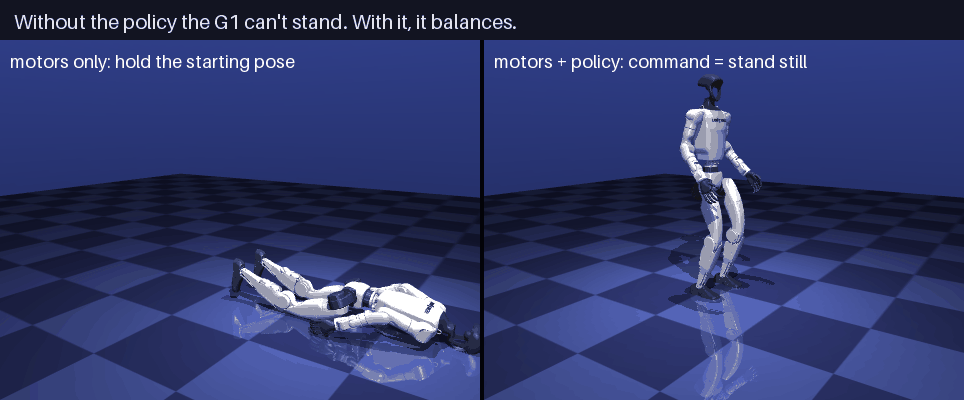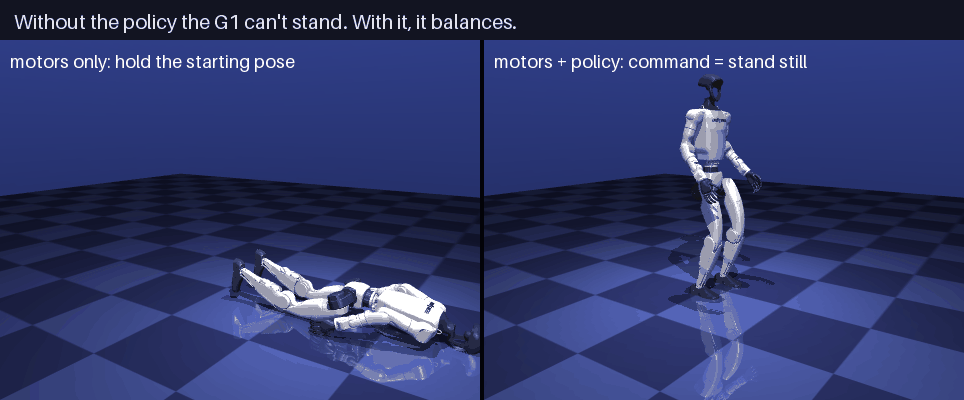
Three parts of the setup took me some time to understand: which parts touch, how the feet grip, and where the motors’ “armature” comes from.
Which parts touch: collision bits
A robot model has two kinds of shapes:
- Visual meshes: detailed 3D models that make the robot look right.
- Collision geoms: simple capsules and spheres that stand in for the body when things touch.
Checking contacts with detailed meshes would be slow, so the G1 uses 33 simple shapes for collisions: 14 small capsules under the feet and 19 others on the legs, pelvis and arms.
MuJoCo uses two numbers per shape to decide what can touch what: contype and conaffinity. Two shapes A and B can collide if:
The & compares the two numbers bit by bit. Think of contype as “the groups I am in” and conaffinity as “the groups I collide with”. If either shape accepts the other, they collide.
| Shapes | contype / conaffinity | Collide with the floor (1 / 1)? |
|---|---|---|
| Collision capsules | 1 / 1 | 1 & 1 = 1: yes |
| Visual meshes | 0 / 0 | 1 & 0 = 0 both ways: no |
The capsules are also 1 / 1 with each other, so the robot’s limbs can hit each other too. MuJoCo skips each body’s direct parent automatically, and a short <exclude> list in the model turns off a few more pairs.
The bits can do more than on and off. The training code has a “no self-collision” option that sets the robot’s capsules to contype = 0, conaffinity = 1:
- Robot and floor: floor
contype1 & capsuleconaffinity1 = 1. They collide. - Robot and robot:
0 & 1 = 0both ways. They don’t.
With one pair of numbers, the feet stay on the ground while the legs can pass through each other.
Friction: how the feet grip
Walking only works if the feet don’t slide. When a foot presses on the floor, the force has two parts: the normal force straight up, and the friction force along the floor. Friction can be anything up to a limit, and the limit grows with how hard the foot presses:
\[|F_{\text{friction}}| \le \mu \, F_{\text{normal}}\]The G1’s feet use \(\mu = 0.6\), about rubber on a hard floor. If you draw the total force as one arrow, this rule says the arrow must stay inside a cone around the vertical, \(\arctan(0.6) \approx 31°\) wide on each side. Inside the cone the foot sticks. Outside, it slips.
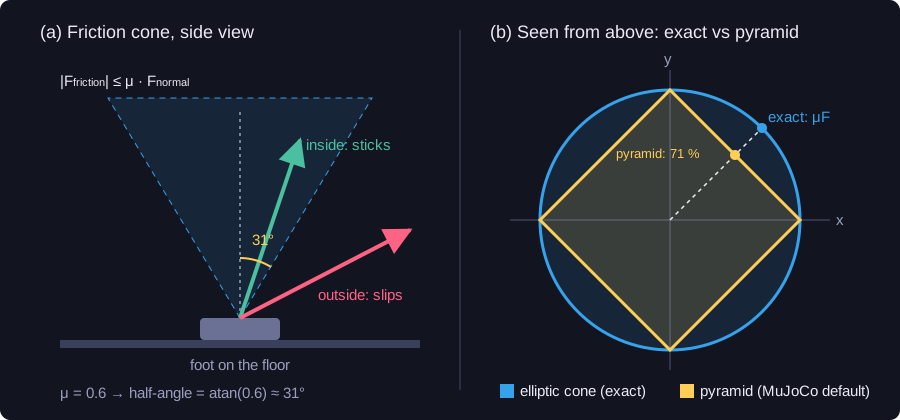
For the 33 kg robot standing still, that is about 196 N of sideways grip. It also limits how fast the robot can speed up: at most \(\mu g \approx 5.9\) m/s². No controller can push harder than the floor allows.
condim sets how many directions a contact can push in:
condim |
Resists | Used for |
|---|---|---|
| 1 | nothing along the floor (no friction) | the robot’s other capsules |
| 3 | sliding in both directions | the feet |
| 4 | sliding + twisting | — |
| 6 | sliding + twisting + rolling | — |
The feet get condim = 3, enough to walk. The other capsules get condim = 1: if two knees bump, they just slide apart, and that is also faster to compute.
Whose friction wins. A foot touching the floor is two shapes, each with its own friction. By default MuJoCo uses the bigger one, so the floor’s 1.0 would beat the foot’s 0.6. So the feet get a higher priority (1, the floor has 0), and the higher-priority shape’s settings are used. Without this, the robot would walk on a grippier floor than the one it was trained on.
Pyramid or cone. A perfectly round cone is slow to solve, so by default MuJoCo uses a pyramid instead. With condim = 3 the pyramid has 4 sides. Seen from above (panel b), the cone is a circle and the pyramid is a diamond inside it. Along the axes they match, but on the diagonals the pyramid gives only 71 % of the real grip. MuJoCo also offers an exact cone, cone="elliptic", which is slower. The training framework (mjlab) uses the pyramid, and so do I: the policy learned to walk with it.
All of this is one small function, apply_collision_settings in g1_utils.py (slightly shortened here):
for geom in spec.geoms:
    if re.fullmatch(FOOT_PATTERN, geom.name):        # the 14 foot capsules
        geom.condim, geom.priority = 3, 1
        geom.friction[0] = 0.6
        geom.contype = geom.conaffinity = 1
    elif re.fullmatch(".*_collision", geom.name):    # other collision capsules
        geom.condim, geom.priority = 1, 0
        geom.contype = geom.conaffinity = 1
    else:                                            # visual meshes: never collide
        geom.contype = geom.conaffinity = 0
Motors and gearboxes
In Week 1, armature was just a number I added to a pendulum joint. On the G1 it comes from real hardware. Understanding it took me longer than anything else in the setup.
An electric motor spins fast but is weak. A gearbox trades speed for strength. With a gear ratio \(N\), the joint turns \(N\) times slower than the motor and gets \(N\) times the torque. The G1 uses planetary gearboxes, each with two stages.
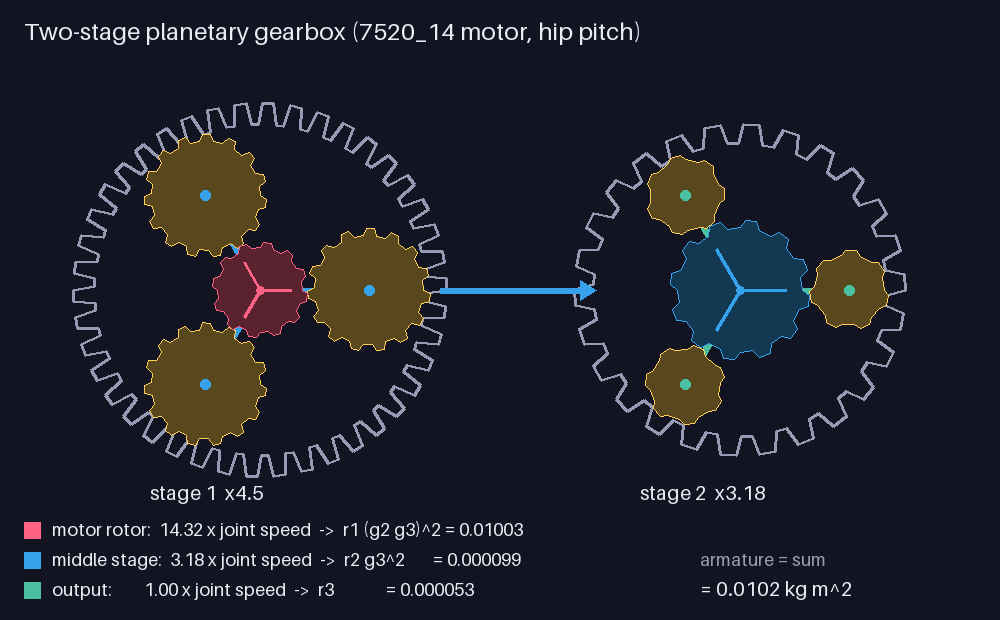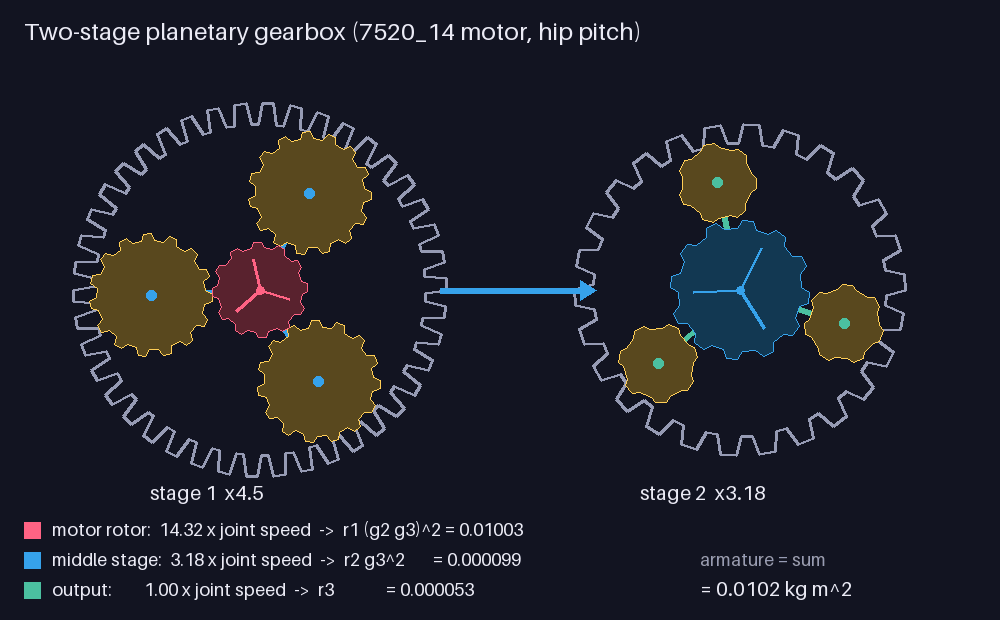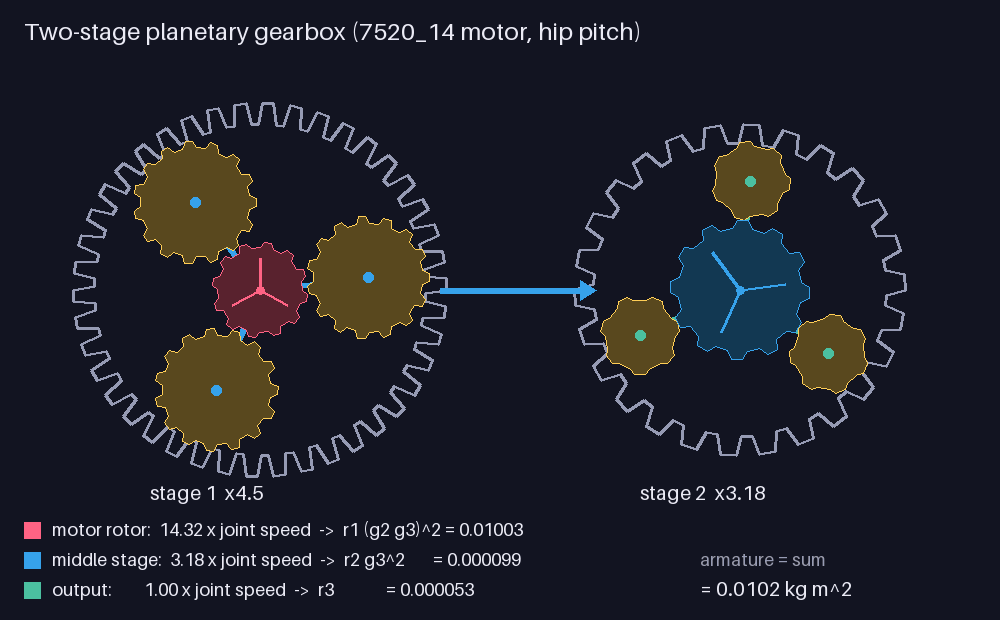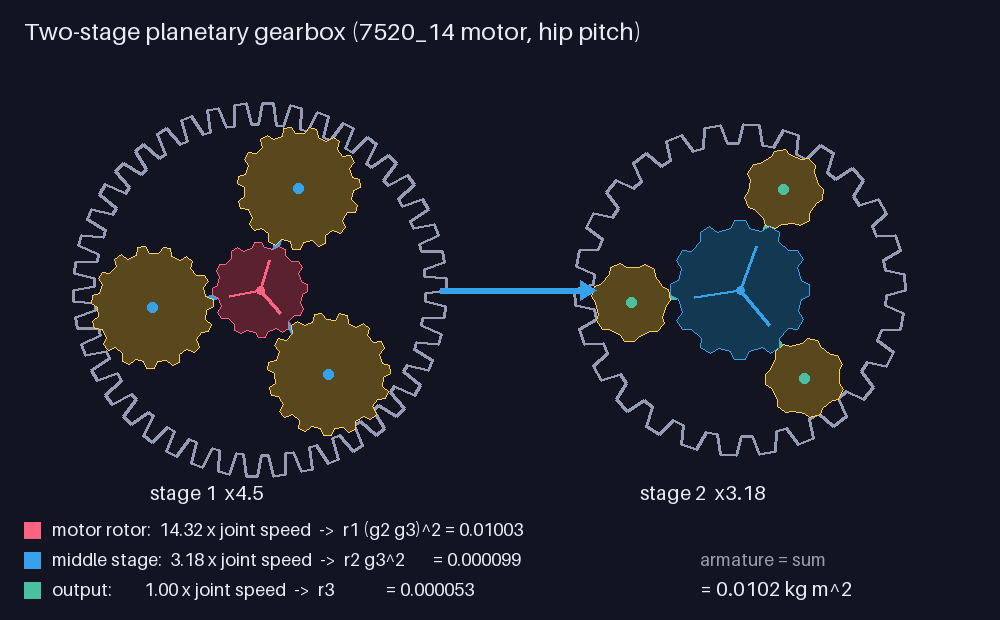
One stage. A planetary stage has a sun gear in the middle (the input), planet gears around it, and a fixed outer ring. The planets sit on a carrier, which is the output. When the sun turns, the planets roll along the ring and drag the carrier round, more slowly. How much slower depends only on the teeth:
\[\text{ratio} = 1 + \frac{\text{ring teeth}}{\text{sun teeth}}\]That explains the odd numbers in the motor specs, like \(1 + 48/22 = 3.18\).
Two stages. In the animation, the motor is the red sun of stage 1. Stage 1’s blue carrier turns 4.5 times slower and drives stage 2’s blue sun. Stage 2’s green carrier is the joint, another 3.18 times slower. The ratios multiply: \(4.5 \times 3.18 = 14.3\). That’s in the motor’s name: 7520_14.
Why the motor feels heavy at the joint. A spinning part stores energy \(\tfrac{1}{2} I \omega^2\). Say a part spins \(k\) times faster than the joint:
\[\tfrac{1}{2}\, I \,(k\,\omega_{\text{joint}})^2 = \tfrac{1}{2}\,(I k^2)\,\omega_{\text{joint}}^2\]So from the joint’s point of view, that part weighs like \(I k^2\). The motor spins \(4.5 \times 3.18\) times faster than the joint, the middle stage 3.18 times, and the output just once. Adding all three gives the armature:
\[\text{armature} = r_1\,(g_2\, g_3)^2 + r_2\, g_3^2 + r_3\]For the 7520_14 (the colored rows in the animation): 0.01003 + 0.000099 + 0.000053 = 0.0102 kg·m². The motor rotor is the lightest part, but it makes up 98 % of the total, because its factor is the biggest: \(14.3^2 \approx 205\).
In code it’s two short functions, in g1_utils.py:
def reflected_inertia(rotor_inertias, gears):
    r1, r2, r3 = rotor_inertias
    g1, g2, g3 = gears
    return r1 * (g2 * g3)**2 + r2 * g3**2 + r3

def motor_gains(armature, natural_freq_hz=10.0, damping_ratio=2.0):
    wn = 2 * np.pi * natural_freq_hz          # Hz -> rad/s
    return armature * wn**2, 2 * damping_ratio * armature * wn   # KP, KD
The G1 has four motor types:
| Motor | Ratio | Armature (kg·m²) | Joints |
|---|---|---|---|
| 5020 | 16.0 | 0.0036 | shoulders, elbows, wrist roll |
| 7520_14 | 14.3 | 0.0102 | hip pitch and yaw, waist yaw |
| 7520_22 | 22.5 | 0.0251 | hip roll, knees |
| 4010 | 25.0 | 0.00425 | wrist pitch and yaw |
The ankles and the waist pitch and roll each use two 5020 motors, so their numbers are doubled.
From armature to gains. The training setup doesn’t tune each joint by hand. It picks the behavior it wants, a 10 Hz natural frequency and a damping ratio of 2, and uses last week’s formulas to get the gains:
\[K_P = I\,\omega_n^2 \qquad K_D = 2\,\zeta\, I\, \omega_n \qquad (I = \text{armature},\ \omega_n = 2\pi \times 10 \text{ rad/s})\]For the hip pitch: \(K_P = 40.2\), \(K_D = 2.56\). The policy file stores the gains it was trained with, and all 29 of mine matched.
What the policy sees
The policy never sees the simulator. Every 20 ms it gets 99 numbers, and that is all it knows about the robot. The order comes from the policy file itself:
| Numbers | What | Where it comes from |
|---|---|---|
| 0–2 | linear velocity | IMU velocimeter |
| 3–5 | angular velocity | IMU gyro |
| 6–8 | projected gravity | pelvis orientation |
| 9–37 | joint positions | qpos[7:] minus the starting pose |
| 38–66 | joint velocities | qvel[6:] |
| 67–95 | last action | the policy’s previous output |
| 96–98 | command | the requested \([v_x, v_y, \omega_z]\) |
In code, from observation_utils.py:
obs = np.concatenate([
    read_sensor(model, data, "imu_lin_vel"),   # velocity of the IMU, pelvis frame
    read_sensor(model, data, "imu_ang_vel"),   # angular velocity, pelvis frame
    projected_gravity(model, data),            # "down" in the pelvis frame
    data.qpos[7:] - default_pos,               # joint angles relative to the starting pose
    data.qvel[6:],                             # joint velocities
    last_action,                               # previous policy output
    command,                                   # [vx, vy, wz]
]).astype(np.float32)
A number in the wrong place, or in the wrong frame, does not cause an error. The policy just reacts to a robot that doesn’t exist. So I checked each part against something I could work out by hand.
Which frame is which
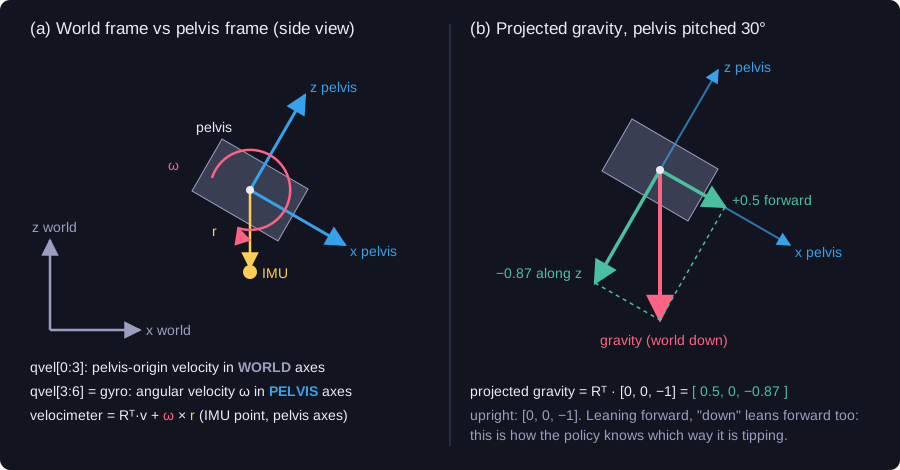
The robot’s base is a free joint, and its velocity qvel[0:6] mixes two frames (panel a):
qvel[0:3], the linear velocity, uses world axes.qvel[3:6], the angular velocity, uses the pelvis’s own axes.
The policy was trained on sensor readings, and both IMU sensors use the pelvis frame: “forward” is always the pelvis’s x axis, whichever way the robot faces. To check I understood them, I rebuilt both sensor readings from qvel:
- The gyro equals
qvel[3:6]. It’s already in the pelvis frame. - The velocimeter needs two steps. First turn the world velocity into the pelvis frame (\(R^\top v\)). Then add \(\omega \times r\), because the IMU sits 9.5 cm from the pelvis centre, and on a turning body, points further out move faster.
Both matched exactly. Leaving out \(\omega \times r\) gave an error of 0.03 m/s, which matters when the robot is asked to walk at 0.5 m/s.
Projected gravity (panel b) is “down” from the robot’s point of view, \(R^\top [0, 0, -1]\). Standing upright it’s \([0, 0, -1]\). Leaning 30° forward it becomes \([0.5, 0, -0.87]\): down now points partly forward. That’s how the policy knows which way it is falling.
def projected_gravity(model, data):
    R = data.xmat[model.body("pelvis").id].reshape(3, 3)   # pelvis frame -> world
    return R.T @ np.array([0.0, 0.0, -1.0])                 # world -> pelvis frame
A 5 ms lag
One detail surprised me. mj_step computes the sensors first and then moves the simulation forward. So right after a step, the joint angles are new, but the IMU readings are still from before the step, 5 ms old. One call to mj_forward updates them.
During normal walking the difference is tiny, 0.004 rad/s. But when the robot hits the floor, its rotation changes sharply, and the old gyro reading was off by up to 11 rad/s. Diego’s code uses the old values. The training framework updates them first (at least in the version I could read). On flat ground it barely changes the walk: 3.00 m against 3.08 m in 6 s.
Inside the network
The trained policy is one file, walk.onnx. ONNX is a standard format for trained neural networks. It stores the steps of the computation and the learned weights, so you don’t need the framework that trained it. The policy was trained in PyTorch, but to run it I only need ONNX Runtime. Diego’s C++ ROS node uses the same file.
I wrote a small reader to see what’s inside:
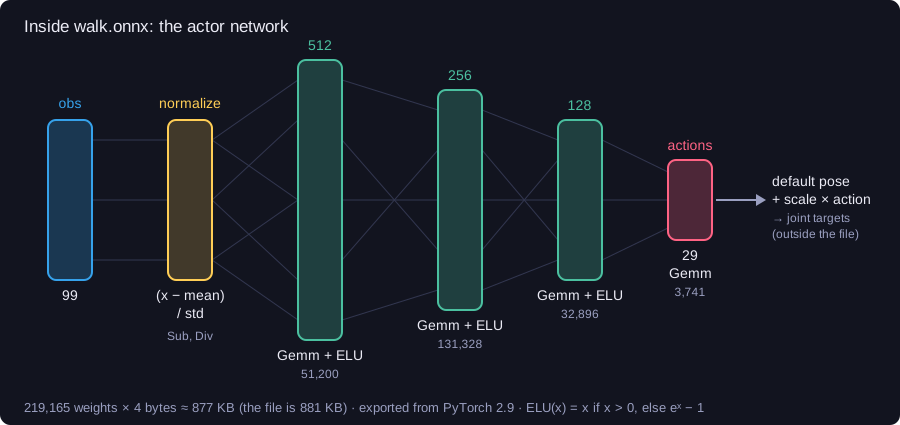
- A normalizer comes first. The network learned on scaled inputs, \((x - \text{mean}) / \text{std}\), and the mean and std from training are inside the file. So I give it the raw 99 numbers. Scaling them myself would scale them twice.
- Then a simple MLP: \(99 \to 512 \to 256 \to 128 \to 29\). Each layer is a matrix multiply plus a bias (ONNX calls it
Gemm), followed by ELU, which is like ReLU but smooth below zero. - About 219,000 weights. At 4 bytes each that’s 877 KB, and the file is 881 KB, so it’s almost all weights.
- Only the actor. Training also used a second network, the critic, which judged how good each moment was. It’s not in the file, because running the policy doesn’t need it.
The file also stores metadata: joint names, starting pose, gains, action scales and the observation order. Loading the policy and reading it takes a few lines, from walk.py:
session = ort.InferenceSession("walk.onnx", providers=["CPUExecutionProvider"])
meta = session.get_modelmeta().custom_metadata_map        # name -> comma-separated values
stiffness = [float(v) for v in meta["joint_stiffness"].split(",")]
I compared every entry with my model. All of them matched. That was the strongest check that my simulated robot is the one the policy was trained on.
It walks
The policy runs every 20 ms, and the physics runs 4 times in between. Here is a simplified version of the controller in policy_utils.py, which is called before every physics step:
def control(model, data):
    if step % 4 == 0:                                      # every 4th physics step = 50 Hz
        obs = make_observation(model, data, default_pos, last_action, command)
        action = session.run(None, {"obs": obs[None, :]})[0][0]     # 99 numbers in, 29 out
        target = default_pos + action_scale * action                 # joint angles, joint order
        data.ctrl[:] = target[joint_index_of_actuator]               # reorder for the actuators
        last_action = action                                         # fed back next time
    step += 1
Two details mattered:
- The policy gives joint angles in joint order, but MuJoCo’s actuators are in a different order (grouped by motor type). So the targets must be reordered.
- My first version was off by one. MuJoCo counts the robot’s free-floating base as joint 0, so a joint’s id is one more than its place in the policy’s list. A simple test caught it: a zero action must give exactly the starting pose.
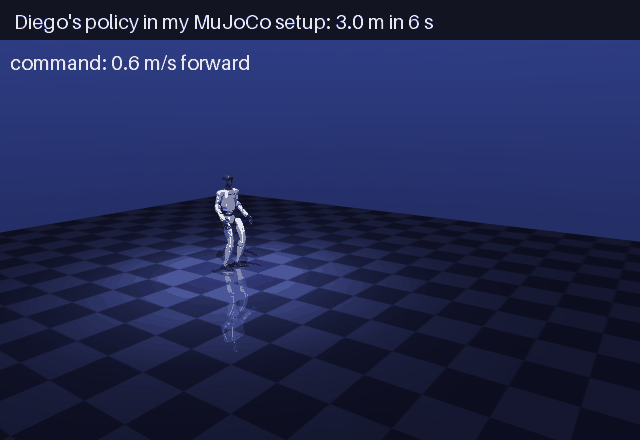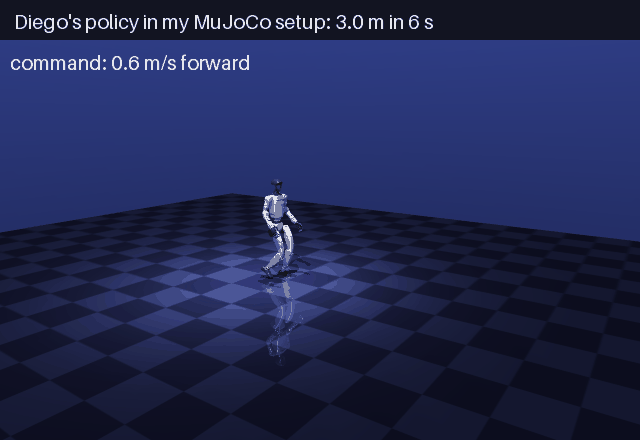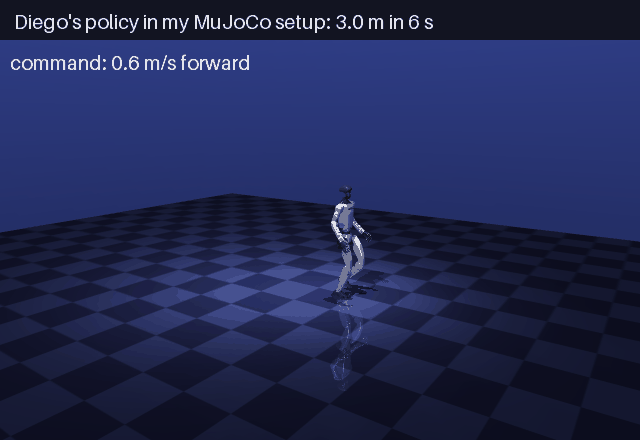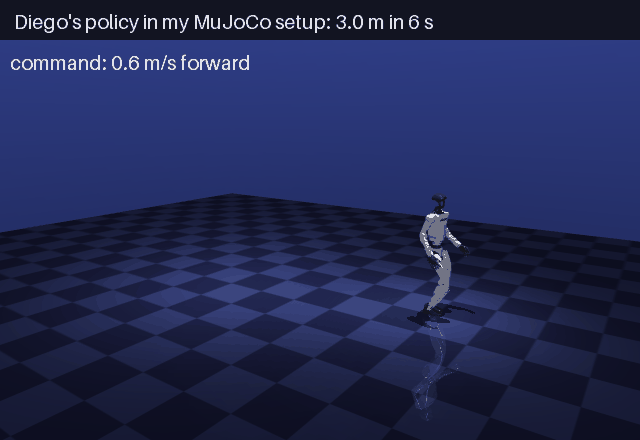
Asked to walk at 0.6 m/s, the robot walked 3.0 m in 6 s without falling, including the time it takes to get going.
The dead zone
Testing every command
Walking forward is just one test. I tried every kind of command: faster, slower, backward, sideways, turning. For each one I measured the steady speed, over the last 3 s of an 8 s run, once the robot had settled into its walk (validate.py):
| Command | Speed reached |
|---|---|
| forward 0.2, 0.3 m/s | 0.00: stands still |
| forward 0.4 / 0.5 / 0.8 m/s | 0.30 / 0.43 / 0.76 m/s |
| sideways 0.3 m/s | 0.00: stands still |
| sideways 0.5 m/s | 0.43 m/s |
| turn on the spot, 0.3 to 0.8 rad/s | 0.05 rad/s at most |
| walk 0.5 m/s while turning 0.5 rad/s | turns at 0.47 rad/s |
Normal walking works well. But below about 0.3 m/s the robot just stands, and it won’t turn on the spot at all, only while walking. A dead zone.
Ruling out my own mistakes
My first thought was that I had done something wrong. So I checked the differences I knew about:
- Sensor timing: old or updated IMU readings (the 5 ms lag) give the same dead zone.
- Integrator: Euler (as in Diego’s code) or implicitfast (the training default) give the same dead zone.
- Command code: the training framework doesn’t cut off small commands.
The dead zone stayed every time. Diego’s blog doesn’t mention it. It seemed to come from the policy itself.
A second policy
Unitree publishes its own walking policy for the G1, trained with the same framework. It takes 98 numbers instead of 99. It leaves out the linear velocity, which a real robot can’t measure directly, and it adds two numbers that Diego’s policy doesn’t have: a gait phase. I gave it its own robot model and starting pose, checked its file the same way, and ran the same tests (unitree.py):
| Command | Diego | Unitree |
|---|---|---|
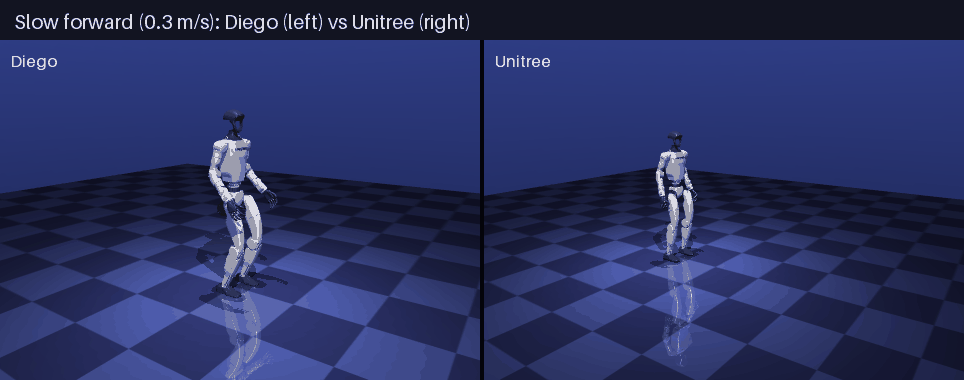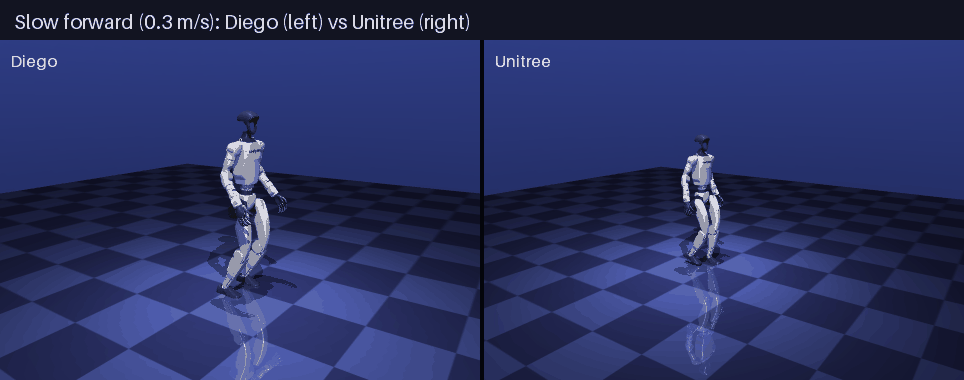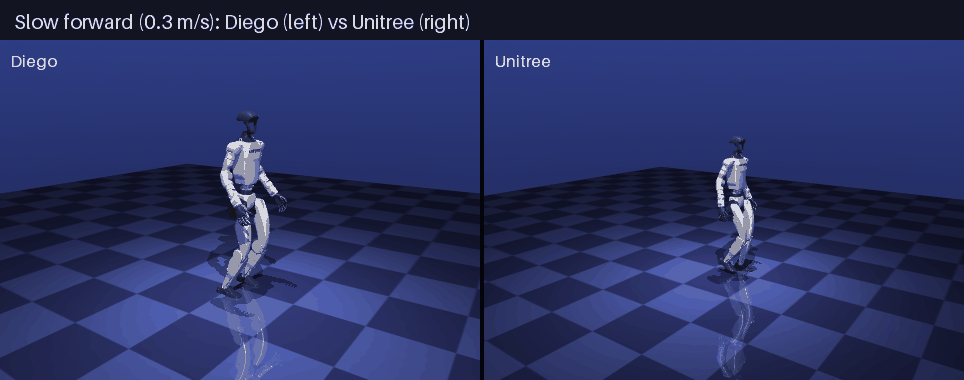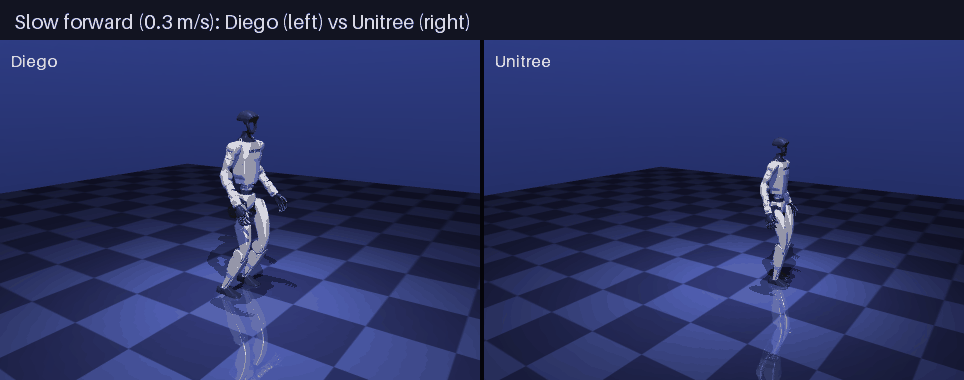
| forward 0.2 / 0.3 m/s | 0.00 / 0.00 | 0.22 / 0.31 m/s |
| forward 0.5 / 0.8 m/s | 0.43 / 0.76 | 0.50 / 0.80 m/s |
| sideways 0.3 m/s | 0.00 | 0.24 m/s |
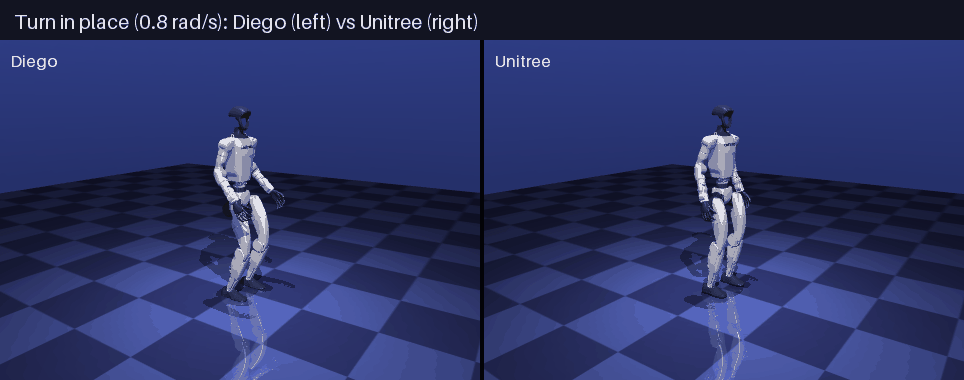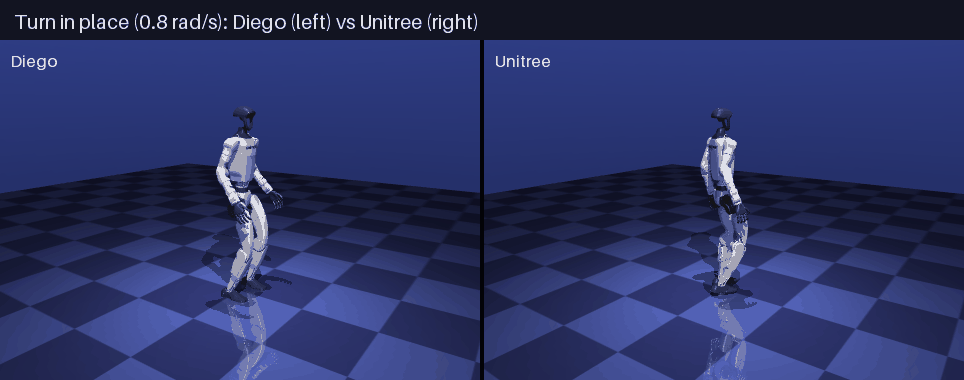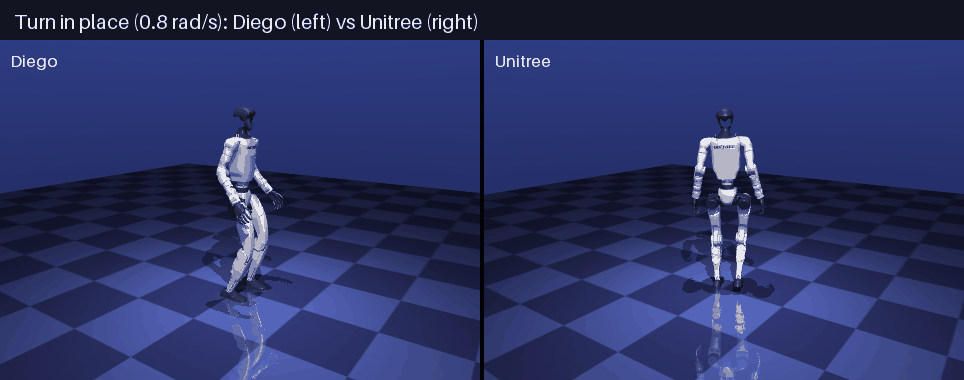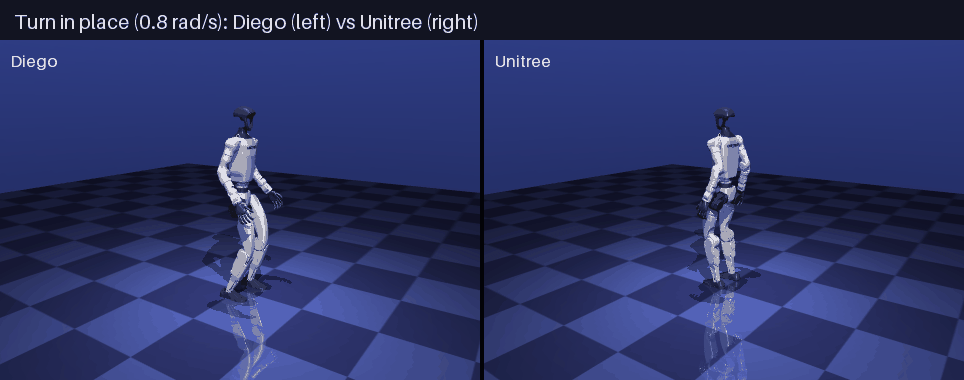
| turn on the spot 0.3 / 0.5 / 0.8 rad/s | 0.01 / 0.01 / 0.05 | 0.34 / 0.53 / 0.81 rad/s |
No dead zone. Unitree’s policy walks slowly, steps sideways and turns on the spot, almost exactly as asked.
The gait clock
The gait phase is a clock that goes round once per step cycle, every 0.6 s. A single number from 0 to 1 would jump back to 0 at the end of every cycle, so instead it’s given as a point on a circle:
\[\phi = \frac{t \bmod 0.6}{0.6}, \qquad \text{phase} = [\sin 2\pi\phi,\; \cos 2\pi\phi]\]When the command is almost zero, the clock is turned off and reads \([0, 0]\). That’s the policy’s signal to stand still. In code, from unitree_utils.py:
def gait_phase(t, command, period=0.6):
    phi = (t % period) / period
    phase = np.array([np.sin(2 * np.pi * phi), np.cos(2 * np.pi * phi)])
    if np.linalg.norm(command) < 0.1:      # standing still: clock off
        phase = np.zeros(2)
    return phase
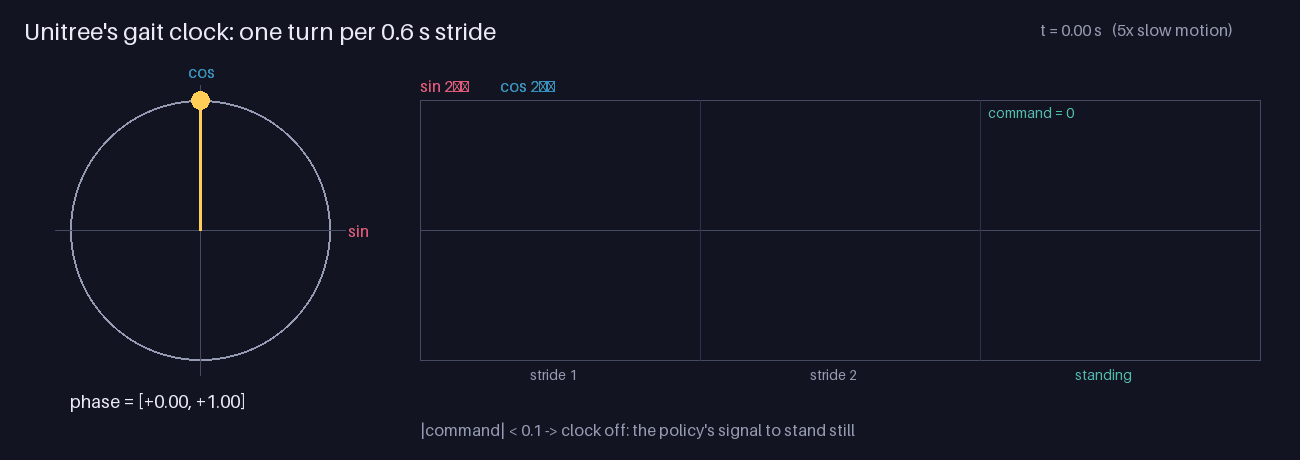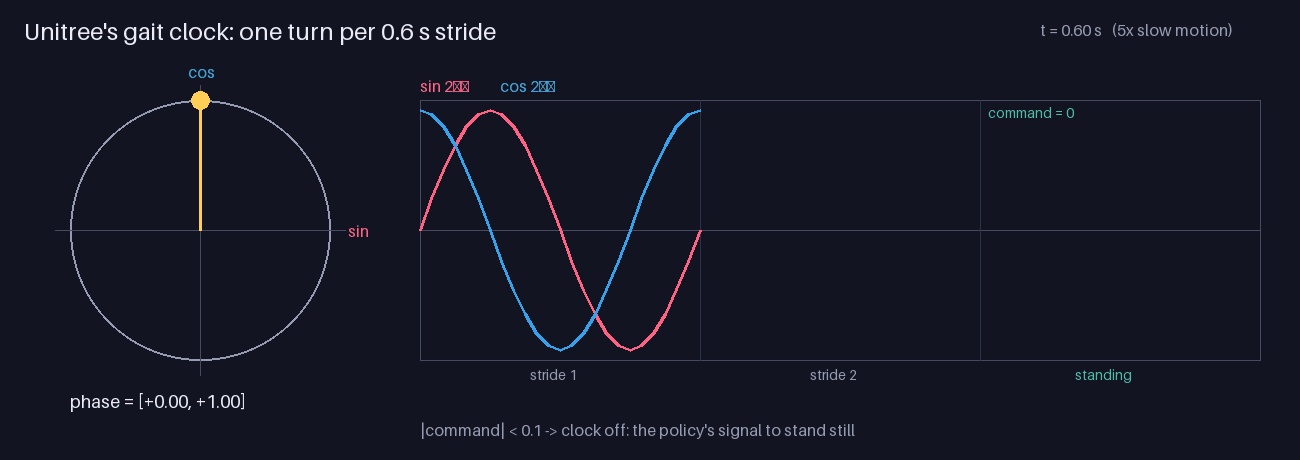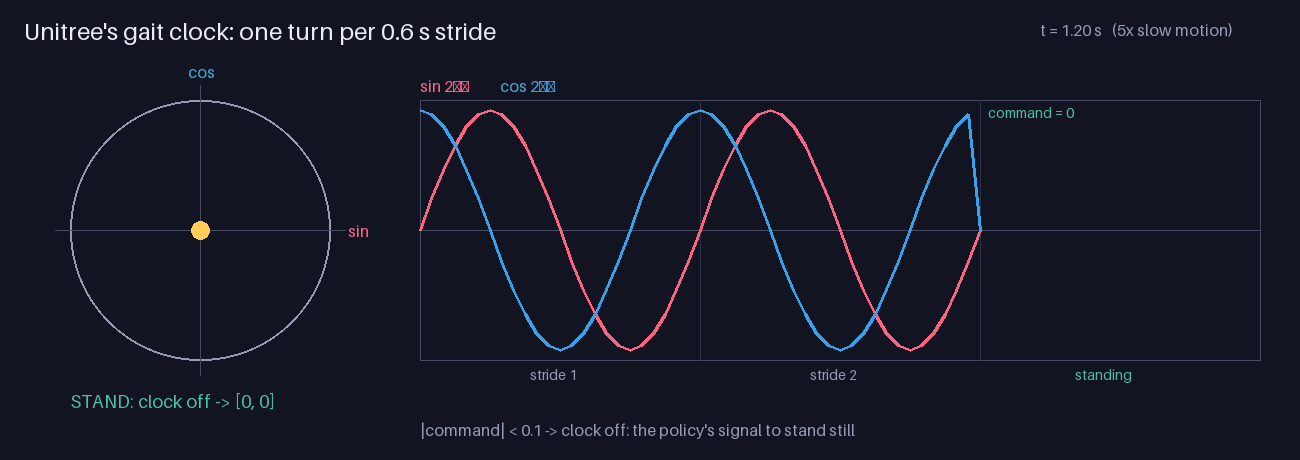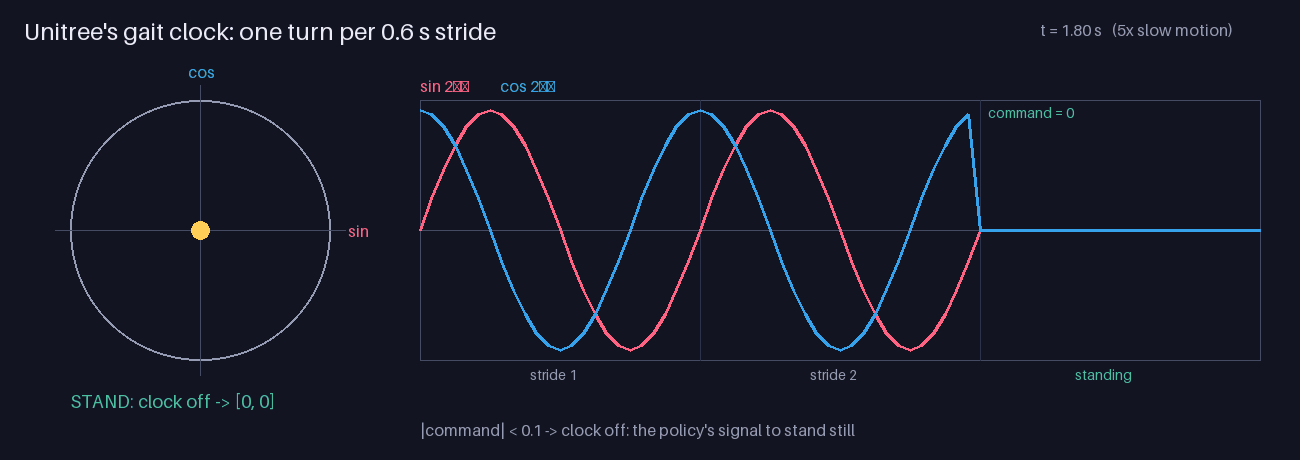
This gave me an idea. A turn-on-the-spot command is \([0, 0, 0.8]\). Its size is 0.8, so Unitree’s clock keeps ticking, which tells the policy to keep stepping. Diego’s policy has no clock. It has to decide from the command alone whether to step, and maybe it only learned to step when the command is large.
The experiment
To test this idea, I changed only the clock and kept everything else the same: same robot, same policy, same commands. I tried three versions of Unitree’s policy:
def with_phase(value):
    def obs_fn(model, data, default_pos, last_action, command):
        obs = make_unitree_observation(model, data, default_pos, last_action, command)
        obs[9:11] = value                  # replace the gait clock
        return obs
    return obs_fn

# normal clock | clock off: with_phase([0, 0]) | clock frozen: with_phase([0, 1])
| Command | Normal clock | Clock off, \([0, 0]\) | Clock frozen at \([0, 1]\) |
|---|---|---|---|
| turn on the spot 0.8 rad/s | 0.81 rad/s | 0.02 rad/s | falls |
| forward 0.3 m/s | 0.31 m/s | 0.00 m/s | 0.48 m/s, too fast |
| sideways 0.3 m/s | 0.24 m/s | 0.00 m/s | 0.17 m/s, unsteady |
| forward 0.6 m/s | 0.60 m/s | 0.54 m/s | 0.73 m/s |
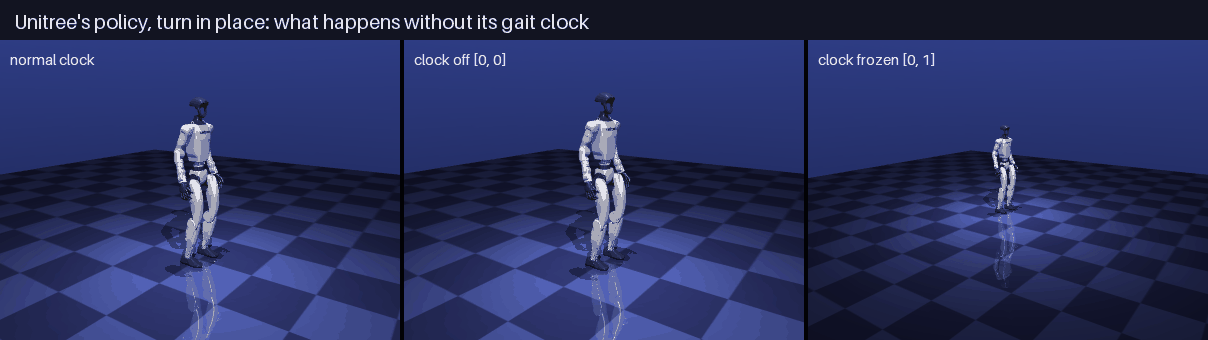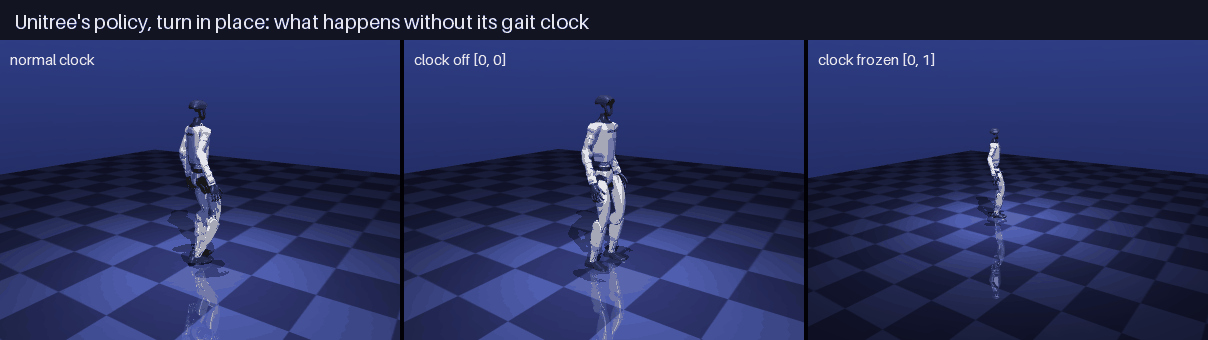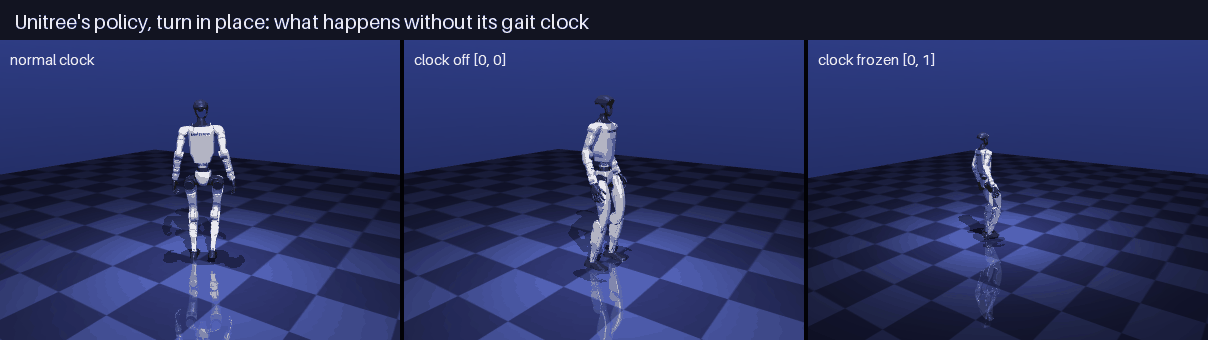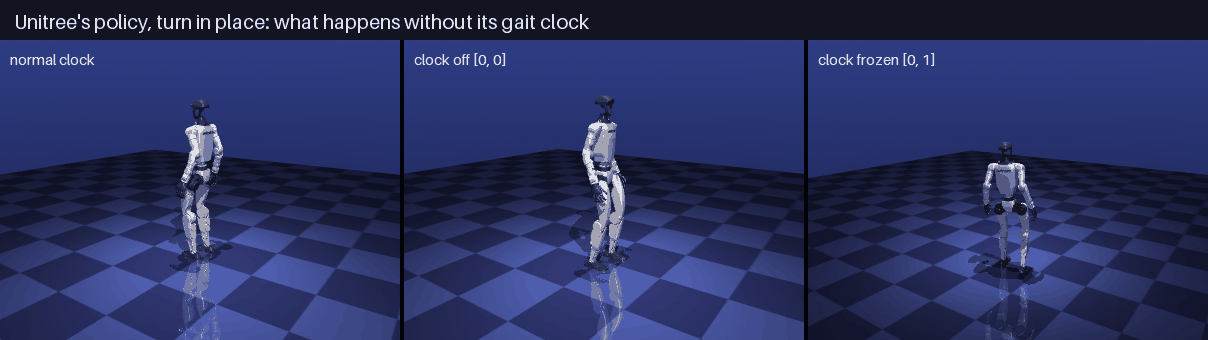
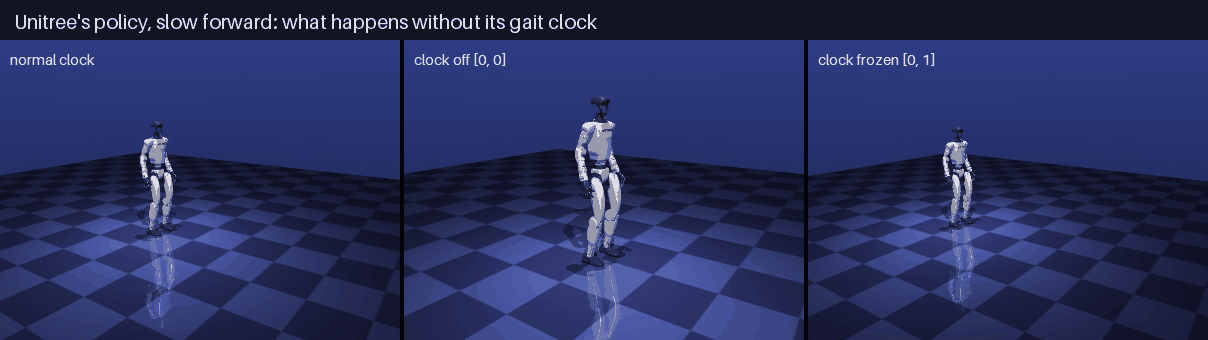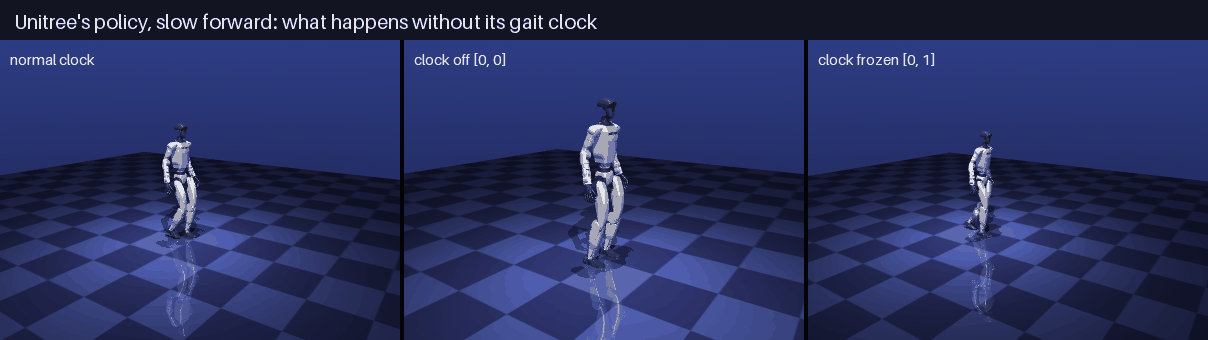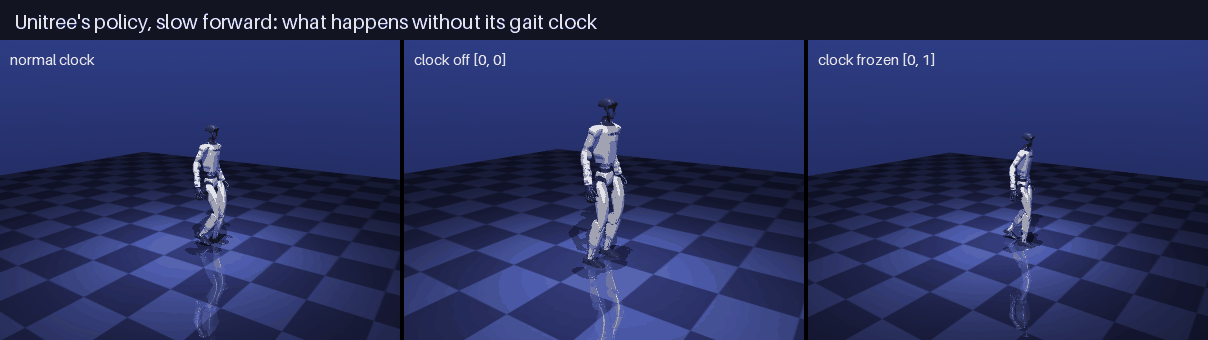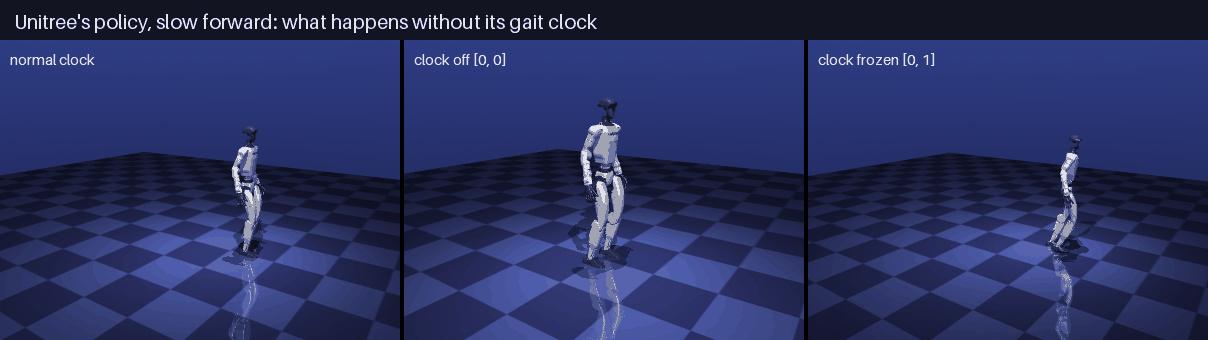
With its clock turned off, Unitree’s policy behaves like Diego’s: it stands still for slow commands, won’t turn on the spot, and still walks at 0.6 m/s. With the clock frozen, it loses its rhythm, goes too fast, and falls when it tries to turn. So the clock has to tick, not just be there.
What I can and can’t say
For Unitree’s policy the answer is clear: the ticking gait clock is what makes it step for small commands. For bigger commands, the command alone is enough.
For Diego’s policy the evidence is strong but indirect. It has no clock, and it behaves like Unitree’s policy without its clock. That’s my best explanation for its dead zone. But it isn’t proof: the two policies were trained with different settings, and Diego’s training settings aren’t available.
Next
- ROS 2 and Gazebo. Diego’s project runs the policy in Gazebo, a different simulator, through a ROS 2 node. I’ll set that up (in Docker on my Mac) and see how much of the behavior carries over.
- Which policy is better? “It walks” isn’t a measurement. I want proper numbers to compare the two policies: how well they follow commands, how much they drift, how much effort they use, and how they handle pushes and different floors.